Context.
A large online gaming and betting operator ran more than 200 business-critical Java services across 30,000+ VMs, spanning AWS and on-premises infrastructure. The platform processed over 180 million casino spins per day (an average of more than 2,000 per second), while total platform traffic peaked at up to 600,000 requests per second. In a regulated real-money environment, observability had become part of the revenue-protection and operational-resilience model.
Monitoring had evolved over a decade: SCOM, VMware and Nutanix for on-premises infrastructure, alongside AWS; AppDynamics and Prometheus for application performance; Logstash and Elasticsearch for logs; and several visualisation platforms. Each tool remained useful, but incidents still had to be assembled across disconnected timelines. The organisation had extensive telemetry without a single path from business impact to technical cause.
Problem Statement.
Outcome/Impact.
Solution.
We framed the programme as controlled modernisation, not a tool replacement. The existing stack stayed active, each service was validated independently, and rollback remained available throughout. This protected business continuity while allowing value to be proven progressively.
Used AI to reduce uncertainty around the critical dependency: AI-assisted analysis mapped the Netty-based TCP library's channel pipeline, custom binary serialisation boundaries, metadata, event-loop thread hand-offs and error paths. Engineers used that evidence to select safe propagation points, verify compatibility and benchmark the change on Java 8 before rollout.
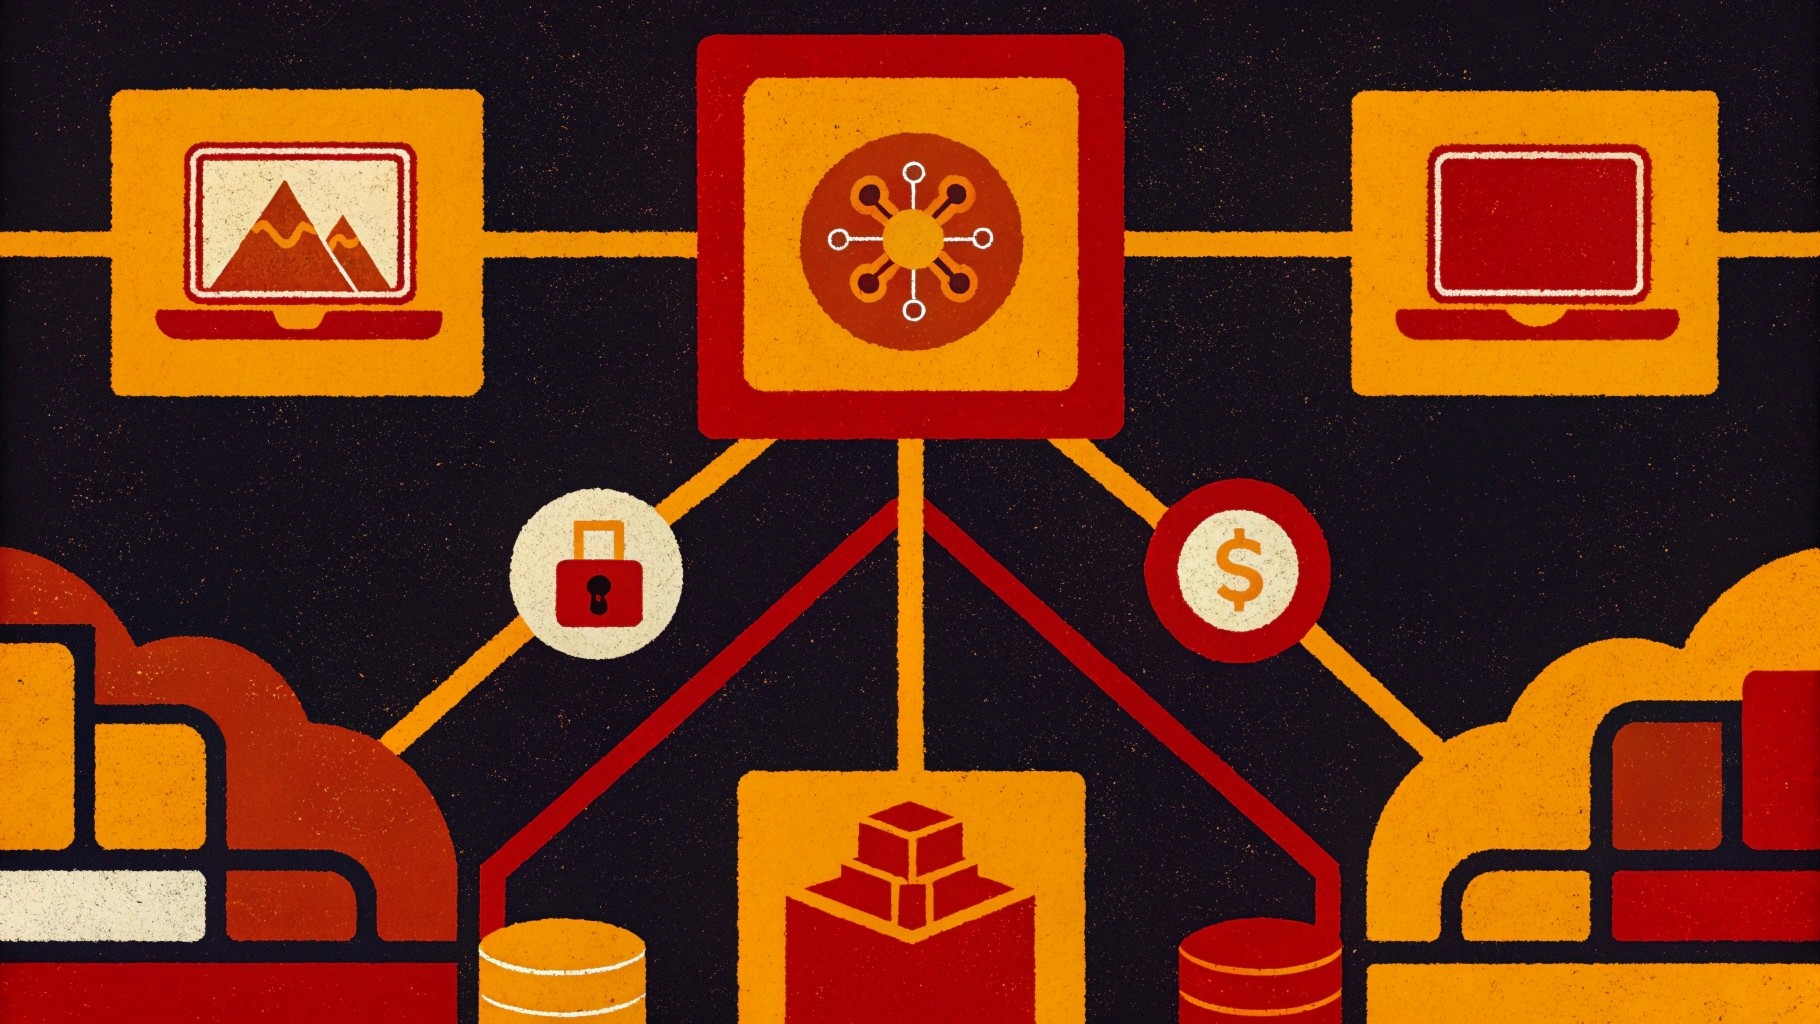
Turned one intervention into an estate-wide capability: OpenTelemetry client and server spans were added to the shared TCP library with W3C trace context carried through its binary protocol. One controlled framework change unlocked end-to-end tracing across 200+ services without redesigning each application.
Moved business detection closer to transaction time: Four bounded streaming metric families for spins, bets, wins and revenue replaced poll-based detection. Detailed logs remained available for audit and investigation, while latency drift, retry growth, queue pressure and spin-rate deceleration provided earlier warning of business impact.
Fleet-wide control with a lean team: Ansible manages the OpenTelemetry Java Agent and local Collector as code across 30,000+ VMs on AWS and on-premises. It keeps every host at its intended state, so versions, configuration and rollouts are changed once and applied everywhere. The fleet scales without adding operations headcount. Batching, retry and export stay outside the application process, and an open instrumentation standard reduces future switching cost.
Scaled the migration with AI assistance: AI mapped legacy monitor definitions across repositories to services, methods, critical user journeys and candidate instrumentation points, then drafted configurations and documentation. Repetitive planning moved from days to hours; engineers retained accountability for semantics, performance and production approval.
Result.
Across AWS and on-premises, the operator moved from fragmented, reactive monitoring to an observability capability aligned with business continuity. The value extended beyond better telemetry: earlier protection of peak-hour revenue, faster detection and automated response, a fleet run by a lean team, and a safer path to modernise a legacy estate. The five-year-stable, Netty-based TCP library was not rewritten; it was understood, instrumented and converted into a platform-wide control point. AI accelerated discovery, while disciplined engineering kept the change safe.